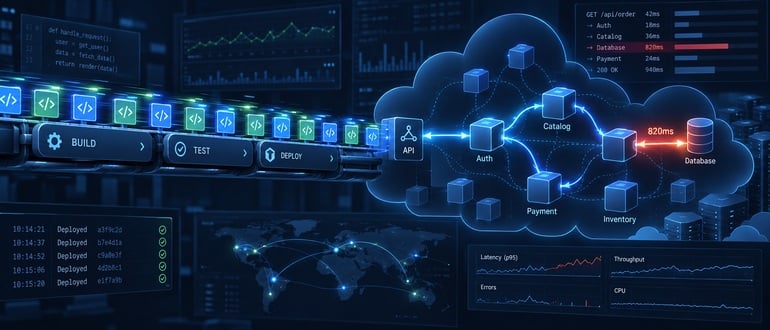
Deployment frequency has become one of the clearest markers of a mature engineering organization. Teams that once shipped monthly now ship daily, and teams that shipped daily now ship several times a day. This shift has largely delivered on its promise. Smaller changes are easier to reason about, rollbacks are faster, and feedback loops are shorter.
What has received less attention is the effect this same shift has had on the practice of debugging performance issues. Several assumptions that previously held, a stable release to compare against, a known change set behind a given incident, sufficient time between deployments to observe a system before the next one lands, no longer apply in the same way.
A Moving Baseline
Performance debugging has traditionally depended on comparison. An engineer examines current behavior against a known good state, typically the previous release, and narrows down what changed. This approach works well when releases are infrequent enough that the previous release remains a stable, well understood reference point.
When deployments occur several times a day, that reference point moves continuously. A regression noticed in production may trace back to any one of a dozen deployments merged since the last time someone reviewed that code path closely. The regression itself is genuine, but the comparison method that once made it straightforward to isolate no longer has a single fixed point of reference.
This does not indicate that frequent deployment introduces more performance issues. It indicates that the traditional method of identifying them, comparison against a known baseline, becomes more difficult to apply as the baseline itself becomes a moving target.
Smaller Changes, More Difficult Attribution
A related effect occurs at the level of individual changes. Smaller, more frequent deployments are generally easier to review and easier to roll back. However, when a performance issue surfaces days after a change was merged, rather than immediately following it, attributing the issue to a specific change becomes a process of elimination across many small deployments rather than an inspection of one larger one.
A single large release makes attribution simpler in one way, since there are fewer candidates to consider, but harder in another, since each candidate is larger and more complex to inspect. Frequent small releases invert that trade off. Each individual change is simple to review, but the number of candidates behind a delayed symptom grows quickly, and a minor dependency update or an altered query parameter buried in a routine pull request is just as capable of causing a regression as a larger architectural change.
Neither approach removes the underlying difficulty. It appears in a different form depending on how a given team ships.
Where Transaction Level Visibility Applies
This is where visibility at the transaction and code level becomes relevant, not as a substitute for deployment history, but as a means of observing what actually occurred at runtime, independent of which release introduced it. A trace showing precisely which method, query, or downstream call consumed the time for a specific slow request does not require prior knowledge of which deployment caused the issue. It identifies the issue directly, within the transaction in which it occurred, whether that turns out to be an unindexed query, a retry loop against a failing dependency, or a serialization step that grew more expensive as payload sizes increased.
This changes the starting point of an investigation. Rather than beginning with an assessment of which among several recent deployments caused a given issue, an engineer can begin with a direct account of where a specific request spent its time, and work backward toward the change that introduced it, informed by observed behavior rather than elimination alone.
Dependency mapping serves a similar function at a structural level. As services are deployed and redeployed independently of one another, understanding which services actually call which, based on current behavior rather than the architecture as documented at the last major review, becomes part of maintaining visibility that keeps pace with the system itself.
Delivery Speed and Diagnostic Speed Are Separate Measures
It is worth being precise about what deployment frequency actually measures. It measures how quickly a team can move a change into production, a genuinely useful indicator of process maturity. It does not measure how quickly that same team can diagnose a performance issue once one appears in production.
These two measures can move independently of one another. An organization may improve deployment frequency substantially while diagnostic time remains unchanged, or even increases, if the practices used to investigate performance issues have not kept pace with how frequently the system now changes. Improving one without corresponding attention to the other tends to produce a team that ships quickly and then spends a disproportionate share of that gained time identifying what went wrong afterward, which is a cost that rarely shows up in delivery metrics themselves.
Keeping both measures aligned generally requires treating runtime visibility as something that keeps pace with deployment frequency itself, present for every service from the point of deployment, rather than something introduced after a service has already accumulated a performance issue worth investigating.
Where This Leads
The practices that enable faster software delivery and the practices that make performance issues easier to diagnose are not inherently aligned. The two require deliberate coordination. This typically involves treating transaction level tracing as part of how a service is deployed, rather than as a separate concern addressed later, so that the same velocity built into shipping code remains available when investigating what that code actually does once it is running. OpManager Nexus provides a 30-day free trial for teams that want to see this kind of transaction level visibility applied to their own environment.